Alignment
这篇博客来聊一个比较重要的概念:对齐 (Alignment)。
在 CPU 执行代码的过程中,一个比较严重的性能瓶颈就是 Back-end Memory Bound(后端访存延迟)。
Intel Haswell 访存延迟参考
为了有个大概的概念,我们先看下 Intel Haswell 架构的具体访存延迟数据:
数据来源: 7-cpu.com - Haswell
配置: Intel i7-4770 (Haswell), 3.4 GHz, RAM 32 GB (PC3-12800 cl11 cr2)
- L1 Data cache: 32 KB, 64 B/line, 8-WAY
- L1 Instruction cache: 32 KB, 64 B/line, 8-WAY
- L2 cache: 256 KB, 64 B/line, 8-WAY
- L3 cache: 8 MB, 64 B/line
具体延迟如下:
- L1 Data Cache Latency:
- 4 cycles (pointer simple access)
- 5 cycles (complex address calculation
n = p[n])
- L2 Cache Latency: 12 cycles
- L3 Cache Latency:
- 36 cycles (3.4 GHz i7-4770)
- RAM Latency: 36 cycles + 57 ns (约 200~300 cycles)
可以看到,从 L1 到主存,后端访存延迟有着数量级的巨大差距。虽然这篇博客的主题不是分析延迟,但对这个量级有一个大致印象是很有必要的。
什么是”对齐”?
我们最常接触到的对齐概念通常来自 C/C++ 中的 结构体对齐。
结构体对齐
规则很简单:
- 结构体中的每一个成员,其 起始地址必须是它自身大小 的整数倍。
- 结构体的 总大小,必须是该结构体中 最大成员对齐模数 的整数倍。
为什么要对齐?
原子性保证 (Atomicity):
不对齐的读取在某些硬件上 不是原子的。硬件可能会将其拆分为两个读取操作。就在这两次读取的微小间隙中,另一个线程可能修改了数据,导致你读到了一半新一半旧的“撕裂”数据(Tearing Read/Write)。硬件兼容性:
某些架构(如早期的 ARM 或一些 RISC 架构)本身就不支持不对齐的读取,强制访问会触发异常。虽然 Intel 在 P6 之后的 CPU 上都保证了一个缓存行内操作的原子性,但这主要是为了兼容性考虑。Intel 开发者手册 9.1.1 Guaranteed Atomic Operations:
The P6 family processors (and newer processors since) guarantee that the following additional memory operation will always be carried out atomically:
• Unaligned 16-, 32-, and 64-bit accesses to cached memory that fit within a cache line.(P6 系列处理器(以及更新的处理器)保证以下额外的内存操作将始终原子地执行:
• 针对缓存内存的未对齐 16 位、32 位和 64 位访问,只要它们完全包含在一个缓存行内。)但在同一手册中,紧接着有这样一句警告:
“However, nonaligned data accesses will seriously impact the performance of the processor and should be avoided.”
(不对齐的数据访问会严重影响处理器性能,应尽量避免。)不过,需要注意的是,随着微架构的进化,这个观点也发生了一些变化。从 Haswell 架构开始,非对齐访问的硬件优化已经做得非常好了。
Agner Fog 在其优化手册中提到:
“There is hardly any penalty for misaligned memory access, except for the effect of using multiple cache lines.”
(除了跨越缓存行带来的影响外,未对齐内存访问几乎不会产生额外惩罚。)所以,我们要讨论的重点,正是这剩下的唯一惩罚——Cache Line 对齐。
Cache Line 对齐
它的核心含义非常明确:避免数据访问跨越两个 Cache Line。
相较于 Cache Line 内部的非对齐读取(现在 CPU 处理得很好),跨 Cache Line 读取的惩罚是非常严重的。
我们知道现代 DRAM 采用 Burst Mode(突发传输),Cache Miss 时一次性读取一个 Cache Line 的数据。如果你的数据因为结构体排列不当体积膨胀,或者数据本身就很大,导致一次访问跨越了两个 Cache Line:
- AGU (地址生成单元) 会将这一条读取指令拆分为 两条。
- LSU (Load Store Unit) 会 串行 地执行这两次读取。
这就是核心区别:一倍的指令开销,成倍的延迟。
性能测试:数据对齐 (Data Alignment)
我们的测试框架与之前的类似:总共读取 1GB 的数据,但我们会将这 1GB 分配在不同大小的 Region(区域)中(模拟 L1/L2/L3/RAM 的场景),并使用不同的 Offset (偏移量) 去读取,观察带宽的变化。
核心测试结构体
1 | struct test |
测试代码
1 | int main(void) |
测试结果
以下是不同对齐偏移(Alignment)在不同区域大小(Region Size)下的带宽数据汇总(单位:GB/s):
| Alignment (Offset) | 8 KB (L1) | 128 KB (L2) | 4 MB (L3) | 1 GB (RAM) |
|---|---|---|---|---|
| 0 (Aligned) | 434.72 | 193.28 | 74.77 | 25.53 |
| 1 | 180.59 | 106.41 | 69.13 | 22.85 |
| 2 | 125.96 | 74.79 | 40.08 | 16.67 |
| 3 | 131.77 | 79.60 | 38.41 | 17.15 |
| 15 | 152.05 | 106.98 | 41.73 | 15.71 |
| 16 | 135.81 | 89.91 | 46.92 | 19.26 |
| 17 | 146.14 | 107.89 | 67.18 | 21.48 |
| 31 | 129.66 | 77.53 | 54.15 | 17.70 |
| 32 (Aligned 32B) | 350.77 | 150.82 | 58.71 | 21.11 |
| 33 | 188.36 | 101.36 | 68.36 | 24.08 |
| 63 | 172.91 | 106.38 | 67.96 | 23.90 |
| 64 (Aligned 64B) | 434.31 | 128.66 | 53.61 | 17.12 |
| 65 | 93.86 | 76.81 | 48.89 | 24.13 |
可视化分析
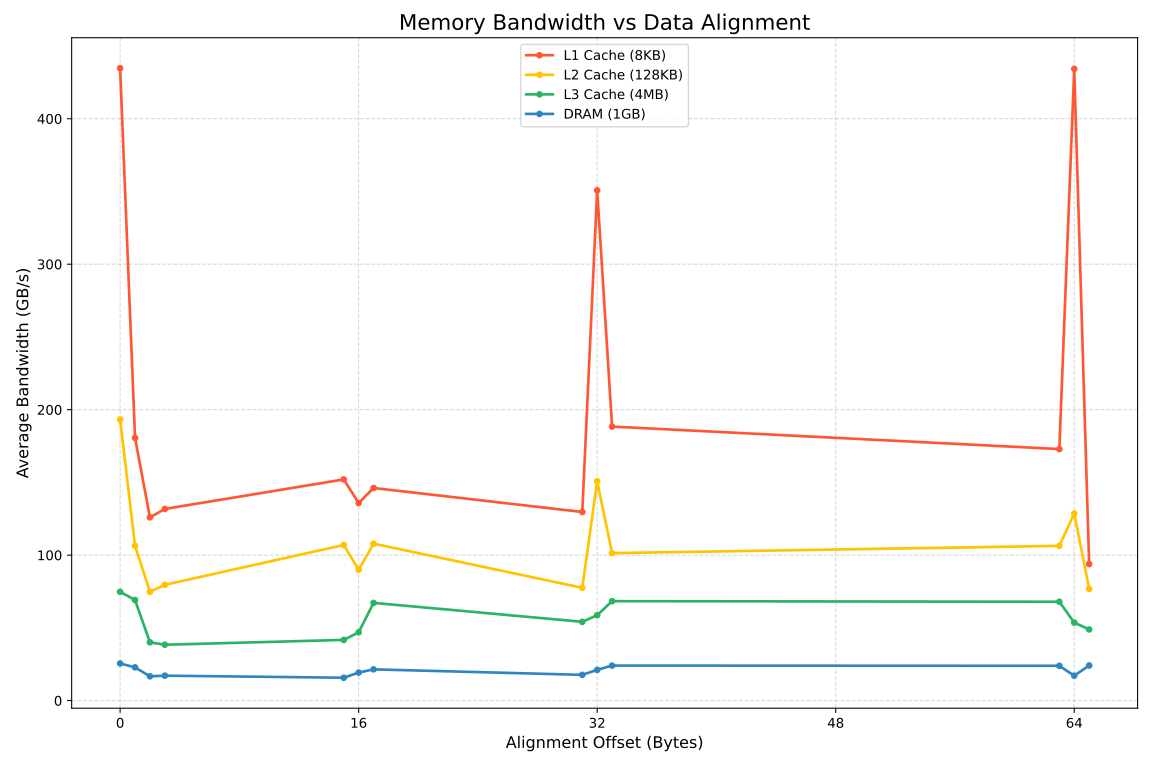
分析结论:
- L1 Cache 下惩罚巨大:可以看到在 8KB (L1 Cache) 区域内,跨 Cache Line 读取(不对齐)带来的惩罚是最显著的,带宽从 434 GB/s 骤降。
- RAM 下惩罚减小:从 L1 到 RAM,不对齐的惩罚比例逐步变小。这是因为主存访问本身的基础延迟(Base Latency)就非常大(几百个周期),相比之下,跨行带来的额外惩罚(虽然也是硬延迟)在总延迟中的占比就没那么夸张了。
- 32B 对齐的特殊现象:
- 在 Alignment = 32 时,带宽明显回升,逼近 0 偏移时的水平。
- 这是因为我们使用的是 AVX (YMM) 指令,单次读取 32 Bytes。
- 当偏移量为 32 时,读取范围是
[32, 63],刚好完全落在一个 64B 的 Cache Line[0, 63]内部,没有发生跨行。因此性能几乎没有损失。
性能测试:指令对齐 (Code Alignment)
上述测试针对的是数据缓存(D-Cache)。但别忘了,指令 (Instruction) 也是数据。
CPU 前端需要从指令缓存(I-Cache)中读取指令字节流。如果跳转目标地址(Jump Target)刚好位于两个 Cache Line 之间,导致 CPU 取指时需要进行跨行读取,同样会产生性能惩罚。
测试方法
我们运行 1G 次循环,循环体逻辑完全一致,但通过在循环前插入不同数量的 NOP 指令,来改变循环体的入口地址偏移。
核心代码
1 | global NOPAligned64 |
测试结果
| Alignment | Min Time (ms) | Avg Time (ms) | Bandwidth (GB/s) |
|---|---|---|---|
| Aligned 64 | 116.93 | 190.90 | 5.24 |
| Aligned 1 | 131.40 | 196.75 | 5.08 |
| Aligned 15 | 122.03 | 186.23 | 5.37 |
| Aligned 31 | 128.84 | 197.96 | 5.05 |
| Aligned 63 | 144.91 | 223.97 | 4.46 |
可视化分析
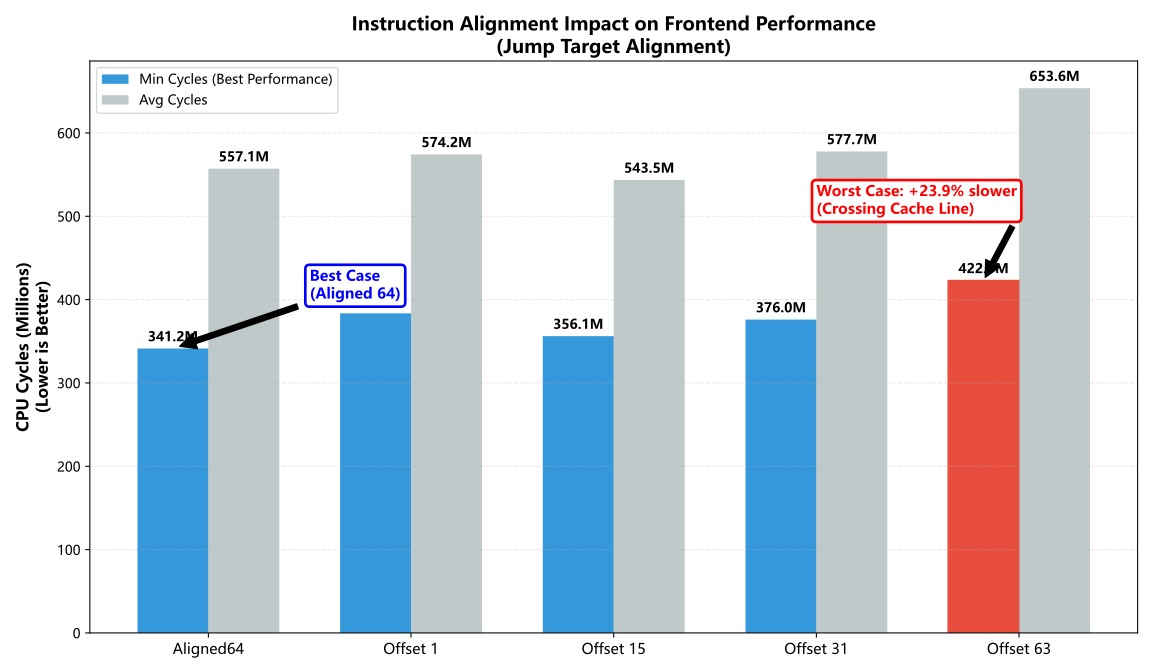
结论:
可以看到,NOPAligned63(偏移 63 字节)的耗时最长,带宽最低。
这是因为循环体的第一条指令 inc rax 等可能刚好跨越了 Cache Line 的边界(或者紧邻边界导致预取效率降低),使得前端取指效率下降。这就是为什么编译器在优化速度时通常会尝试将循环头或函数入口对齐到 16 或 32 字节边界,是一种以空间换时间的策略。
总结
对齐(Alignment)是高性能编程中必须关注的细节。
- 结构体对齐:现代 CPU 对非对齐访问的惩罚已经很小,主要是原子性保证。
- Cache Line 对齐(数据):这是性能杀手。跨 Cache Line 的原子读取 需要 AGU 拆分指令并串行执行,导致吞吐量大幅下降,尤其是在 L1 Cache 命中率高的情况下。
- Cache Line 对齐(指令):循环体或函数入口如果跨越 Cache Line,也会拖慢前端取指速度。
本文测试代码来源: github.com/cmuratori/computer_enhance